

Adding engineers to a debt-laden codebase doesn’t pay down the debt — it inherits it, since every new hire has to learn the shortcuts baked into every module before writing a line of code. Delivery slowdowns aren’t automatically a technical-debt problem — they can be coordination overhead, a capability gap, or a genuine capacity ceiling, and headcount only helps in the last one (and even then, debt delays the payoff by 4–6 weeks). The article gives a framework for diagnosing which constraint you’re actually in, what real delivery ownership of debt looks like versus ticket execution, how to evaluate whether a delivery partner will work honestly in a messy system, and a 30/60/90-day benchmark for whether debt remediation is actually working.
- 1 Engineering teams spend 20–40% of their time on unacknowledged, unprioritized technical debt — that's time not spent building.
- 2 Adding people to a debt-heavy codebase doesn't reduce the debt — new engineers inherit it, and onboarding cost is closer to six weeks of unavoidable context, not two weeks of standups.
- 3 Brooks's Law still holds: adding people to a late project makes it later, and debt compounds this by layering coordination cost on top of an already-complicated system.
- 4 Delivery slowdowns come from three distinct constraints — coordination overhead, capability gap, or capacity ceiling — and only the capacity ceiling is actually solved by headcount.
- 5 Even in a genuine capacity ceiling, debt delays the throughput gain from new hires by 4–6 weeks — headcount won't save a deadline three weeks out.
- 6 Real delivery ownership means flagging debt blockers with a cost estimate and a fix, not noting them in a ticket and moving on — ticket execution lets debt grow silently, sprint by sprint.
- 7 Evaluate a delivery partner by how they behave when debt surfaces mid-sprint — ask about accountability, estimation, escalation, and what they produce before writing any new code.
- 8 Use a 30/60/90-day benchmark: Day 30 should produce a debt map, Day 60 should show stable velocity plus at least one remediated item, Day 90 should show a documented account of what was addressed versus deferred and why.
Technical debt is the hidden tax on every engineering decision you’ve ever shipped under pressure. In a McKinsey survey of CIOs at large companies, leaders reported that 10 to 20 percent of the technology budget meant for new products goes to fixing tech-debt problems instead. That money isn’t building anything. It’s paying for choices teams made when speed mattered more than structure.
This article is for CTOs and VPs of Engineering who know the debt is there, aren’t sure how to quantify it, and are under pressure to ship faster — usually from the same direction that created the debt in the first place.
What this article covers:
Why the conventional response to delivery slowdowns — adding people — makes debt worse before it makes anything better
The three real constraints slowing your team, and which one debt actually belongs to
What delivery ownership looks like in a codebase carrying significant debt
How to evaluate a delivery partner’s willingness to work in and improve a debt-laden system
A 30/60/90-day benchmark for measuring whether debt remediation is actually working
The Myth They Believe
When a CTO is staring at a slipping roadmap and a codebase full of shortcuts, the instinct is to staff up. More engineers means more throughput means the debt gets paid down and the features ship. The math is clean in a planning doc.
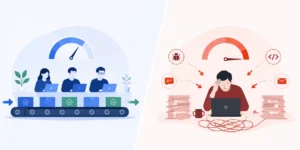
The problem is that debt doesn’t behave like an open workstream. It behaves like friction — and friction scales with the number of people moving through it. A new engineer onboarding into a debt-heavy codebase doesn’t reduce the debt. They inherit it. Every module they touch, they have to understand the shortcuts baked in before they got there. Every integration point is a potential landmine. The onboarding cost isn’t two weeks of standups — it’s six weeks of context that simply cannot be accelerated, regardless of seniority.
Frederick Brooks named this in The Mythical Man-Month (1975), and it has held up across five decades of software projects: adding people to a late project makes it later. The communication channels increase exponentially; a team of five has ten pairs, a team of ten has forty-five. In a normal codebase that’s a coordination cost. In a debt-laden codebase, it’s a coordination cost layered on top of every system that’s already more complicated than it should be.
Stripe’s 2018 survey on developer productivity found that developers spend 33% of their time on technical debt — and estimated that equates to approximately $85 billion in lost productivity globally. That’s not a figure about bad engineers or bad decisions. It’s a figure about compounded shortcuts at scale.
The Three Real Constraints
Technical debt shows up in delivery slowdowns, but delivery slowdowns don’t always mean technical debt. Before you start a remediation program, get clear on which constraint you’re actually in.
Constraint 1: Coordination Overhead
Definition: The team is spending more time managing communication, alignment, and hand-offs than building.
Symptoms:
- Standups run over without resolving blockers
- PRs sit for 48 hours before first review — consistently, not occasionally
- Two engineers build overlapping solutions because ownership was unclear
- Decisions that should close in one day require four people and two meetings
What it is NOT: Coordination overhead is not the same as technical debt, though the two often appear together. A debt-heavy codebase increases coordination cost because nobody fully understands the system. But you can have coordination problems in a clean codebase, too. If removing the debt doesn’t clarify ownership and interfaces, the coordination problem persists.
Constraint 2: Capability Gap
Definition: The work requires depth of knowledge the team doesn’t currently have — and can’t develop fast enough to hit the deadline.
Symptoms:
- The same architectural question gets reopened every few sprints
- Estimates balloon 3× or more during implementation, not at planning
- Engineers can’t articulate the tradeoffs in decisions they made six months ago
- Debt remediation keeps getting scoped out because nobody knows where to start
What it is NOT: A capability gap is not a motivation problem. Engineers who are capable but disengaged behave differently from engineers who are genuinely out of their depth on a debt problem. One needs context and pairing; the other needs better work. Conflating them leads to the wrong intervention — which, in a debt context, usually means more meetings.
Constraint 3: Capacity Ceiling
Definition: The team has the skill and the coordination structure, but not enough throughput to hit the deadline given the scope — including the scope of the debt sitting underneath the feature work.
Symptoms:
- Velocity is stable and predictable across sprints, with no wild swings
- Engineers can scope and estimate the backlog accurately — including the debt items
- PRs merge within 24 hours with no pattern of delay
- The only variable is time: there’s more to do than the current team can do it
The only scenario where headcount actually helps — and the caveat: Capacity ceiling is the one constraint where additional engineers move the needle. But even here, the debt creates an onboarding cost that delays the throughput gain by four to six weeks. If the deadline is three weeks out, headcount won’t save it. If the timeline is measured in quarters and the ownership structure is clean, adding people at the right interfaces can work.
What Delivery Ownership Actually Looks Like
There’s a real difference between two kinds of teams in a debt-laden codebase. One owns delivery. The other executes tickets while the debt quietly piles up.
A team that owns delivery treats debt as part of the delivery problem. It isn’t someone else’s problem for a future sprint.
When they hit a debt-related blocker, they flag it with a cost estimate and a proposed fix. For example: “This will add two days, and here’s why.” They don’t just log it in Jira and move on.
They also know which modules carry the most risk. When a deadline is tight, they plan the work to avoid the worst of it. And they raise architectural concerns during planning, not in the retro.
A team that executes tasks in the same codebase treats debt as background noise. Each ticket is done when the PR is merged — regardless of what was left behind. New debt gets added because fixing the old debt wasn’t in the acceptance criteria. When something slows down because of a structural problem, they escalate it upward and wait. The debt grows sprint by sprint, and the cost of that growth doesn’t appear anywhere in the velocity chart.
The gap between these two patterns isn’t talent. It’s accountability structure. When nobody owns the codebase’s health as a deliverable — not just individual features — the team optimizes for what gets measured. What gets measured, usually, is tickets closed. Debt isn’t a ticket. It’s the absence of tickets that should exist.
30/60/90-Day Delivery Health Benchmark
| Milestone | Healthy Sign | Warning Sign |
| Day 30 | Team has produced a debt map — a written inventory of the highest-risk modules, with an initial estimate of remediation cost and a recommended sequence for addressing them alongside feature work | Team is three weeks in and has not yet characterized the debt they’re working in — “we’re still getting familiar with it” |
| Day 60 | Velocity is stable across two sprints; the debt map has been updated with actual findings from implementation; at least one significant debt item has been remediated as part of delivered work, not deferred | Velocity is inconsistent; debt items keep getting scoped out of sprints; team is building on top of known problems because “fixing them wasn’t in scope” |
| Day 90 | Team has shipped at least one milestone end-to-end, with a written note in the delivery summary on which debt items were addressed, which were deferred, and why | Team has delivered features but the codebase is in worse structural shape than when they started — new code has added complexity rather than reducing it |
| Month 6 | The proportion of sprint time spent on debt remediation versus feature work is documented and tracked; the team is proactively proposing architectural improvements based on pattern recognition across their work | The team is productive by velocity metrics but the debt load has grown — the delivery is measured in tickets closed, not in system health improvement |
If warning signs appear at Day 60, the intervention is specific: require the team’s tech lead to produce a written debt impact assessment within one sprint cycle — not a status update, a document that names the three highest-risk modules, the current cost of not addressing them in terms of delivery days per sprint, and a proposed remediation sequence. If that document cannot be produced within five business days, the engagement is running without the technical ownership the work requires.
Working on the Debt, Not Around It
Innostax takes on delivery engagements in codebases with existing debt. The first two weeks of every engagement include a debt characterization — a written inventory of the highest-risk areas, with a recommended sequence for addressing them alongside feature work, not instead of it. The named tech lead owns that document and updates it each sprint.
Milestone payments are tied to shipped, reviewed output — including debt remediation that was committed to. Not to hours logged or tickets moved.
If you’re carrying significant technical debt and trying to figure out whether to address it before scaling the team or alongside it, the details of how we structure that are at innostax.com.
Actively evaluating options right now? innostax.com