

Choosing between staff augmentation and a dedicated team is not a hiring decision — it’s an ownership decision. Staff augmentation adds capacity inside your existing coordination model; a dedicated team takes ownership of a defined delivery scope, including architecture calls and risk escalation. Most delivery failures trace to one of three constraints — coordination overhead, a capability gap, or a capacity ceiling — and only a capacity ceiling actually improves with more headcount. This guide gives you a diagnostic to identify which constraint you have, a 30/60/90-day benchmark to catch a mismatched engagement before it compounds, and a growth-stage framework for picking the right model at each phase. Get the ownership structure right, and the “just add more engineers” instinct usually resolves itself.
- 1 Staff augmentation vs. dedicated team is a question of ownership structure, not hiring speed — the wrong call shows up in month four, not week one.
- 2 Of the three real constraints on delivery — coordination overhead, capability gap, capacity ceiling — only capacity ceiling scales with headcount; the other two get worse with more people.
- 3 Brooks' Law still holds: adding engineers to an already-late, poorly-bounded project increases coordination cost faster than it adds output
- 4 A team that owns delivery surfaces risk three sprints early and treats handoff documentation as a day-one deliverable, not a contract-end afterthought.
- 5 Day 30 and Day 60 — not month four — are when a mismatched engagement first becomes visible; the 30/60/90 benchmark exists to catch it while it's still cheap to fix.
The Myth: You Are Comparing Two Hiring Models
When a delivery bottleneck appears, the comparison feels obvious: staff augmentation gives you engineers fast, dedicated teams give you a whole squad. You weigh the day-rate, estimate the ramp time, check the contract terms, and make a call. That logic is defensible — and it is also why the wrong decision gets made routinely at exactly the moment it costs the most.
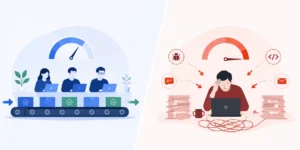
What you are actually comparing is not two hiring models. You are comparing two ownership structures. Staff augmentation adds execution capacity inside your coordination model — engineers join your sprint, follow your architecture, attend your standups. A dedicated team takes ownership of a defined delivery scope: the architecture decisions, the escalation path, the handoff quality. That distinction does not appear in a day-rate comparison. It shows up in month four when a contract engineer leaves and takes six weeks of undocumented context with them — or when a dedicated team surfaces an architectural risk that your roadmap had not priced in.
The research supports the structural framing. DORA’s research on loosely coupled teams — teams with clear ownership boundaries who can make decisions and ship without fine-grained coordination across other teams — has repeatedly found that this capability drives higher deployment frequency and lower change failure rate. Adding headcount to a poorly bounded system compounds the coordination cost rather than reducing it.
The Three Real Constraints Headcount Cannot Fix
Before choosing a model, diagnose what is actually breaking. Most delivery failures trace to one of three constraints — and each one responds differently to the augmentation vs. dedicated team question.
Constraint 1: Coordination Overhead
The cost of keeping engineers aligned — meetings, clarifications, blocked PRs, context re-establishment after switching tasks.
Symptoms:
- Standups run long but decisions still require a follow-up Slack thread
- Engineers block each other on API contracts or shared services more than twice per sprint
- Senior engineers spend more than 30% of their week unblocking junior engineers rather than shipping
- Sprint velocity drops as headcount rises
What it is NOT: A communication culture problem. Adding a better standup template does not fix coordination overhead caused by unclear ownership boundaries. Brooks’ Law — articulated in Fred Brooks’ The Mythical Man-Month (1975), and repeatedly validated by subsequent research — states that adding engineers to a late project makes it later because each new engineer increases the number of communication channels that must be maintained. Augmenting headcount into a high-coordination-overhead environment makes the problem worse.
Constraint 2: Capability Gap
Missing expertise in a specific domain — a particular technology, architecture pattern, or system integration — that the current team does not hold.
Symptoms:
- A single engineer is the only person who understands a critical subsystem
- Technical decisions get deferred because no one on the team has done it before
- Architecture reviews surface the same unresolved risks across multiple sprints
- Vendor integrations or infrastructure migrations stall repeatedly
What it is NOT: A training problem. A capability gap that is blocking delivery requires targeted expertise now, not a six-month upskilling plan. This is one scenario where staff augmentation with a very specific brief can be the right call — provided the knowledge transfer protocol is contractually defined before the engagement starts.
Constraint 3: Capacity Ceiling
The team has the right skills and clear ownership, but there is genuinely more work than available engineering hours.
Symptoms:
- Backlog growth consistently outpaces sprint completion with no coordination drag
- Engineers are fully utilised but not blocked on each other
- Architecture is stable; the bottleneck is pure throughput
- Roadmap commitments are pushed not because of uncertainty, but because of time
The only scenario where headcount directly helps — with one caveat: Capacity ceiling is the only constraint where adding engineers produces proportional output gains. The caveat is onboarding cost. Even in a capacity-ceiling scenario, each new engineer requires 4–8 weeks before they are contributing at full velocity. That ramp cost must be factored into the delivery timeline before any headcount decision is made.
What Delivery Ownership Actually Looks Like
A team that owns delivery behaves in observable ways that are distinct from a team that executes tasks. Ownership shows in how a team communicates risk. They surface a dependency conflict three sprints ahead of when it will block delivery — not the Friday before the release. They deliver status updates that include what is at risk, not just what is on track. When a scope assumption turns out to be wrong, they come with a revised plan, not a revised timeline. They own the handoff: documentation, repository access, test coverage, and deployment runbooks are not an afterthought at contract end. They exist at the start.
A team that executes tasks also behaves in observable ways. They complete what is in the sprint and close the ticket. Status updates describe what was done, not what is at risk. When a blocker appears, they raise a flag and wait for a decision from your side. Architecture questions go up the escalation chain rather than being resolved inside the team. Code review comments are addressed but not synthesised — the same class of issue appears across multiple PRs without anyone naming the pattern. At contract end, knowledge transfer is compressed into a handoff document that was written in the last two weeks of the engagement.
This is a structural problem, not a talent problem. Labelling it a talent problem leads to the wrong fix — replacing engineers who are operating exactly as their contract incentivises them to. The ownership structure is set by how the engagement is scoped, how accountability is defined, and whether the partner has skin in the outcome. Fixing that requires a different engagement model, not a different hiring search.
Patterns to stop — specific to CTO/VP behaviour:
| Pattern to Stop | Why It Hurts Delivery |
| Reviewing PRs as the primary quality gate | Creates a bottleneck at your level. Ownership teams have internal review layers — your review should be architectural, not line-by-line |
| Accepting weekly status updates without a risk register | Good news in every update is a signal of broken escalation, not smooth delivery. Require explicit risk items in every status report. |
| Letting onboarding run without a defined milestone | Ramp time expands to fill available time. A defined 2-week or 4-week onboarding milestone forces both sides to establish what “productive” looks like. |
| Treating architecture decisions as your responsibility to initiate | If the delivery partner is not bringing architecture proposals to you, they are executing, not owning. Reverse the expectation: proposals should come up, approvals should come down. |
| Renewing on relationship rather than delivery data | Continuation based on rapport rather than velocity, defect rate, and milestone adherence rewards execution culture, not ownership culture. |
How to Evaluate a Delivery Partner
Most CTOs evaluate a delivery partner on skill signals: portfolio, tech stack depth, team CVs. Skill is table stakes. What you are actually evaluating is outcome ownership — how the team behaves when something goes wrong, who makes architecture calls, how uncertainty is communicated, and what happens to your codebase when the engagement ends. These things do not appear in a portfolio. They appear in how a partner answers specific questions before the contract is signed.
| Area | What to Ask | Red Flag Answer |
| Accountability | Who is accountable when a sprint milestone is missed — and what does that process look like? | “We work collaboratively to adjust the timeline.” (No named owner, no defined consequence.) |
| Estimation | Walk me through how you would estimate a feature with three external API dependencies. | “We will give you a detailed estimate after we review the spec.” (No methodology described, no assumptions named.) |
| Escalation | Give me an example of a time you surfaced a risk to a client before it became a problem. What did that look like? | “We flag issues as they come up.” (No specific example, no defined escalation path.) |
| Architecture | Who on your team would make the call on whether to use a monolith vs. microservices for our use case — and what would drive that decision? | “That depends on your requirements.” (No architecture judgment offered; question deflected back.) |
| Onboarding | What does your onboarding process look like, and what does the client have to provide for it to work? | “We’re pretty flexible and can adapt to your process.” (No defined onboarding structure; will default to your coordination overhead.) |
30/60/90-Day Delivery Health Benchmark
Onboarding is the highest-risk period of any new delivery engagement. Most problems that surface at month four were visible at day thirty — but not measured. Use this benchmark to separate healthy onboarding from a team that is quietly falling behind.
| Milestone | Healthy Sign | Warning Sign |
| Day 30 | Team has shipped at least one scoped deliverable, repository access is confirmed client-side, and the first architecture decision has been documented with rationale. | Still in “discovery” with no shipped output. Onboarding tasks are open. Architecture questions are being escalated to you rather than resolved internally. |
| Day 60 | Sprint velocity is stable and predictable. Risk items are appearing in status updates with proposed mitigations. The team is raising questions proactively, not reactively. | Velocity is inconsistent. Status updates contain only completed items. You are still answering more questions than you are receiving proposals. |
| Day 90 | The team is operating with minimal CTO/VP touchpoints on day-to-day execution. Escalations are architectural or strategic, not procedural. | You are still reviewing PRs at the line level. Escalations are frequent and involve decisions the team should be making independently. |
| Month 6 | Codebase documentation is current. The team has proposed and shipped at least one architecture improvement beyond the original scope. Knowledge is distributed across the team, not held by one engineer. | Documentation was never established. A key engineer has left and left a knowledge gap. Scope creep is being driven by the team rather than surfaced as a risk. |
If warning signs appear at Day 60: do not wait for Day 90. The path is specific. First, request a delivery retrospective — not a status update — where the team walks through what is behind, why, and what changes in sprint structure or ownership definition would fix it. If the retrospective produces a revised plan with named owners and dates, continue. If it produces a restatement of current status, you have identified a task-execution culture that will not self-correct. At that point, the question is whether to restructure the engagement terms or replace the partner — and that decision is better made at Day 60 than at month four.
The Decision Framework by Growth Stage
The right model is not fixed — it changes as your product and team mature.
| Stage | Right Model | Why |
| Pre-product / MVP | Dedicated team with a defined scope | You cannot afford coordination overhead. A single team that owns the full build — architecture, delivery, and handoff — moves faster than a fragmented augmentation model at this stage. |
| Post-launch / scaling | Dedicated team for core product; augmentation for specific capability gaps | Core product velocity requires ownership continuity. Augmentation is appropriate for bounded, expertise-specific needs (e.g., a security audit, a mobile layer) with a clear handoff protocol. |
| Hypergrowth / parallel workstreams | Augmentation with strong documentation requirements | Coordination overhead grows quadratically with team size. The only structural fix is clear ownership boundaries between pods — not more headcount managed by a single coordination layer. |
| Maintenance / optimisation | Augmentation with strong documentation requirements | If the system is stable and the work is incremental, augmentation is cost-effective — provided repository access, documentation, and knowledge transfer protocols are contractually defined upfront. |
A Note on How Innostax Works
Innostax operates on an outcome ownership model — each engagement has a named tech lead who owns architectural decisions and delivery accountability, not a project manager relaying between your team and a remote bench. What that looks like in practice: client-owned repositories from day one, plain-language risk summaries in every status cycle, defined onboarding milestones, and a two-week risk-free trial so the ownership dynamic is demonstrated before a long-term commitment is made.
If you are currently evaluating delivery partners and want a second opinion on how a specific engagement should be structured, we are easy to reach — Talk to Us.