

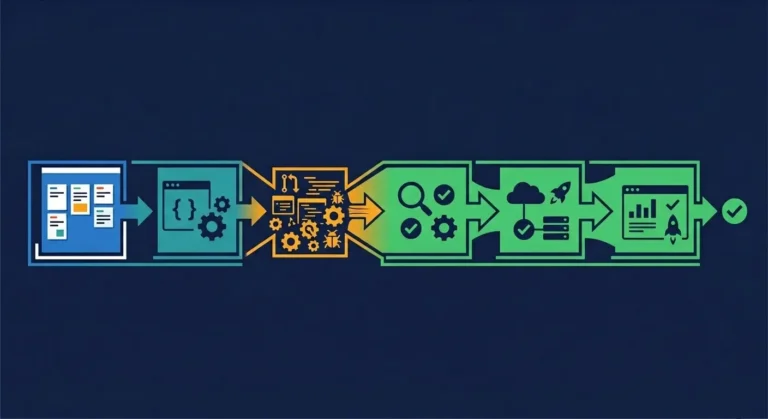
A slow engineering team is almost never a people problem. It’s a systems problem — in your project management process, your code review pipeline, your QA environment, or your team coordination. This guide gives you a structured six-step diagnostic framework to identify exactly where the bottleneck is and fix it without replacing your team. At Innostax, we’ve applied this framework across 50+ engagements. One client reduced median bug-fix time from 180 days to under 2 weeks — not by replacing their developers, but by fixing their QA process and addressing technical debt systematically. Most velocity problems are solved at the diagnosis stage. Once you know the root cause, the fix is usually straightforward.
- 1 A slow engineering team is a symptom. The cause is almost always in one of four places: project management, code review, code quality, or QA.
- 2 Tickets taking more than 3 days to move from dev to QA is a reliable signal that tasks are too large and poorly scoped.
- 3 A single code reviewer for a 7–8 person team is a structural bottleneck — code review capacity must scale with team size.
- 4 QA that depends on developers for requirements context instead of reading source requirements directly will find bugs based on the wrong standard.
- 5 Median bug-fix time of 180 days dropped to under 2 weeks in one Innostax engagement — the fix was QA process and a systematic refactoring policy, not new engineers.
- 6 Replacing engineers before fixing the system is the most expensive mistake a CTO can make.
The Real Meaning of “Slow”
Before diagnosing anything, define what slow actually means in your context.
“Slow” is not a feeling. It is a measurable gap between what was committed and what was delivered. A team is slow when committed items are not shipped within the timeline. If no strict commitments exist, there is no real measure of slow.
Most CTOs who describe their team as slow are experiencing one of three specific symptoms:
- Features are in QA longer than expected — a sprint closes and the ticket still hasn’t passed QA
- Tickets keep bouncing between dev and QA — a feature is “done” multiple times before it actually ships
- Production issues are eating sprint capacity — the team is firefighting bugs instead of building features
Each symptom points to a different root cause. The diagnostic framework below maps each symptom to its source and exact fix. Work through the steps in order. The bottleneck is almost always at the earliest failing step.
The Innostax Engineering Velocity Diagnostic
Step 1: Start With Your Project Management Board — But Only If It’s Trustworthy
The first thing to check is your Jira board (or equivalent). But before you read the data, ask a harder question: is this board trustworthy?
A Jira board that isn’t used diligently gives completely false signals. Tickets may be updated infrequently. Acceptance criteria may be vague. QA feedback might not be logged properly. If this happens, the board tells a story that hides the real problem.
A trustworthy project management board has these properties:
- Tickets are written in a consumable format — clear requirements, specific acceptance criteria, assumptions, edge cases, and linked Figma designs where relevant
- Tickets are the right size: At Innostax, a ticket should take a maximum of three days to move from dev to QA. If a ticket takes longer, it is far too large. It should be an epic, broken into much smaller tasks. Each task must have its own clear acceptance criteria.
- Estimates come directly from developers: They should never be assigned top-down. A developer reads the requirements and asks questions. A developer who self-estimates is far more likely to hit that target. Always build proper estimation time into sprint planning. It is not overhead, it is vital insurance.
- All state changes are logged — every time a ticket moves between dev, QA, and back, it’s recorded with a reason
If your board lacks these properties, fix them first. Everything measured downstream will be highly unreliable until the board reflects reality.
The 3-Day Rule. If a ticket takes more than three working days to reach QA, it is too large. Break it down immediately. This single discipline removes massive coordination overhead. It makes sprint velocity perfectly predictable.
Step 2: Audit Your Code Review Pipeline
Code review is the phase most CTOs incorrectly skip when diagnosing slow teams. It sits between development and QA without an obvious owner. However, a blocked code review pipeline reliably causes bad sprint misses. This is a structural problem, not an individual one.
The questions to ask:
1. How many people are reviewing code?
A single reviewer covering an 8-person team is a major bottleneck. The entire team’s output gets stuck behind one person’s availability. Code review capacity absolutely must scale with team size. You should have at least two to three available reviewers. Aim for a target turnaround of under one business day.
2. Are PRs bouncing back to developers before QA?
Every round-trip between a developer and reviewer adds latency. Reviewers might leave extensive comments requiring rework. This usually means acceptance criteria were unclear. It could also mean the developer skipped a self-review, or the reviewer is applying hidden standards. All three issues result in PRs taking days to merge.
3. Are the right tools being used?
Automated static analysis, linting, and test coverage checks are vital. They catch mechanical issues before a human reviewer ever opens the PR. Reviewers should never spend time on formatting or obvious logic errors. If they do, they’re doing work that should be fully automated.
Step 3: Measure First-Time-Right Rate
Once the board is trustworthy and the code review pipeline is clear, check one important metric. Measure exactly how many times each ticket bounces between dev and QA.
This is the first-time-right rate. It is the percentage of tickets that pass QA on the very first review.
| First-Time-Right Rate | What It Signals |
| 80%+ | Healthy. Focus on planning and throughput. |
| 60–80% | Moderate code quality or acceptance criteria issues. Addressable. |
| Below 60% | Systemic issue — likely code quality, unclear requirements, or both |
If your first-time-right rate is low, the cause is one of two things:
A. The Code Quality is the Problem.
The codebase has accumulated heavy technical debt. Touching one component easily breaks another. Developers submit work that passes their own review, but it quickly fails QA because hidden ripple effects occur.
This requires dedicated sprint capacity to fix properly. The compounding cost of deferred code cleanup consistently exceeds the short-term cost of fixing it now. In systems with distributed microservices, this problem compounds further. Developers simply cannot see the downstream impact of changes without proper interfaces.
For example, Innostax worked with a B2B SaaS platform with over 900 interconnected modules. The codebase had reached a state where every change broke something else. The team had no automated tests and inadequate manual testing. The result was zero features shipped in a year, despite having 20+ engineers.
The fix was not firing personnel. We did two to three sprints of structured refactoring. We applied a strict “touch it, refactor it” policy to every subsequent change. We also built a proper QA process from scratch. Velocity recovered completely within two months.
Signs your code quality is the root cause:
- Bugs tend to appear in areas adjacent to the change, not in the change itself
- Developers regularly say “I didn’t expect that to break”
- Code review is slow because reviewers can’t confidently assess impact
B. The Developer Is Making Mistakes, But the Code is Fine.
Have a direct, open conversation with the developer. Look closely at the specific bugs that caused the bounce. Are they edge cases that are genuinely hard to predict? Or are they simple issues that a thorough self-review would easily catch? The answer determines if this is a skill issue, an attention issue, or a requirements issue.
One important nuance: if tickets bounce frequently on edge cases, QA is doing a good job. However, it usually means requirements didn’t specify how those edge cases should be handled. The fix is upstream in how tickets are written, not downstream with the coder.
Step 4: Audit Production Bug Volume
The fourth diagnostic lens is your exact production bug rate.
If half your sprint is consumed by production bug fixes, your QA process is failing. It is not your development team’s fault. Developers shipping bugs to production is a QA problem first, and a dev problem second.
There are two common causes of high production bug volume:
A. QA Isn’t Testing Against the Right Standard.
This is the most underappreciated cause of production bugs. It is rarely about QA competence. Often, QA is excluded from critical client and stakeholder discussions. Requirements flow loosely from client to PM to developer. QA receives this context second-hand.
The core problem: QA tests against the developer’s loose interpretation, not the client’s strict expectation. Bugs slip through because QA was blindly testing for something slightly different.
The fix: QA absolutely must be present in key requirement discussions and refinement sessions. They are the final vital checkpoint before production. Their understanding of “correct” needs to form straight from the source.
B. QA Isn’t Testing Thoroughly Enough.
This is usually a capacity or process issue. QA teams under extreme pressure to close sprints fast will cut corners. The fix is to explicitly protect QA time during sprint planning. QA sign-off must be a hard requirement before any ticket is done.
C. Staging and Production Are Not the Same.
This is a heavily underdiagnosed cause of bugs. If a production bug cannot be replicated in staging, your environments are sadly not equivalent. QA is passing features that work perfectly in staging but fail under production conditions. This is usually due to different data volumes, server infrastructure, or third-party APIs.
The fix here is not to test harder. It is to fix your environment parity first. Once staging accurately mirrors production, a massive proportion of production bugs simply disappear.
What the data looks like in practice: In one Innostax engagement, a team had a median bug-fix time of 180 days. It took six whole months to resolve customer issues. The root causes were a bad QA process and a fragile codebase. We aggressively implemented structured QA, automated testing, and a refactoring policy. The median bug-fix time rapidly dropped to under two weeks. The exact same engineering team was retained, but the broken system around them was fixed.
Step 5: Check for Coordination and Ownership Gaps
If steps 1–4 don’t reveal the core problem, the issue is team coordination.
Ask these three vital questions:
1. Does every developer own a complete feature?
Velocity completely spirals down when multiple developers share ownership without a clear lead. Work gets duplicated and blockers heavily accumulate. Integration issues blindly appear at the end of the sprint. At Innostax, each developer owns a complete feature flow. Frontend and backend splits are fine, but the ownership boundary must remain explicit.
2. Is the tech lead an information bottleneck?
The tech lead is the primary contact for clients. This is appropriate, but it creates risk. Vital context from client conversations can easily get stuck with the tech lead. When developers lack context, they miss hidden risks. They surface these as bugs later instead. Key architectural decisions absolutely must be documented in the ticket, not kept in the tech lead’s head.
3. Are timezone gaps blocking work?
In distributed setups, offshore developers hit blockers that require onshore client input. Timezone gaps turn a quick one-hour question into a massive one-day block. The fix is twofold. Engineers must be empowered to make safe decisions without constant approval. Also, a clear escalation path must rapidly resolve crucial blockers within hours.
The Flat Team Problem: We frequently see flat structures where developers work independently without a lead. In one engagement, a product manager was forced to manage every individual developer directly. There was no one to resolve technical blockers. The team appeared terribly slow. Replacing this flat structure with a dedicated tech lead fully resolved the problem.
Step 6: Sprint Planning Discipline
Velocity problems that aren’t in code quality, code review, or QA are almost always traceable to sprint planning.
Specifically: committing to more work than the team can actually complete.
Good sprint planning has four components:
1. Capacity-Based Scoping. The tech lead scopes the sprint based on actual, realistic team capacity. This accounts for meetings, leave, and heavy context-switching. It relies on actual available hours this sprint, not theoretical capacity. Agile teams that estimate based on real capacity ship much more predictably.
2. Proper Priority and Scope. The product stakeholders strictly define what matters most. The tech lead defines exactly how much can realistically be delivered. When a founder sets both priority and scope blindly, commitments become dangerously aspirational. The team looks slow because they were severely over-committed.
3. Minimal Task Dependency. Tasks should be distributed so no developer is blocked waiting for another. Dependent tasks must be sequenced correctly. The core dependency should be fully completed before the next task begins. If parallel work is required, the exact interface must be clearly agreed upon beforehand.
4. Merge Conflict Management. In teams of five or more, messy merge conflicts become a major source of lost time. Sprint planning absolutely must account for this. Branches should be kept very short-lived. Integration should happen daily. Task distribution must minimize overlap between developers working in the exact same code areas.
The Managed Team Difference: One Lead Changes Everything
One consistent finding across Innostax engagements is incredible efficiency. Massive coordination overhead disappears instantly when a single tech lead owns the team’s entire output.
In one engagement, a digital agency shifted from managing four developers to interfacing with one tech lead. This brilliantly reduced project management overhead by 75%. Project managers redirected that heavy capacity strictly to client strategy. The tech lead expertly handled sprint coordination and blocker resolution. Both sides did their jobs much better.
In a separate engagement, a SaaS founder moved from incredibly slow releases to near-daily feature shipping. They switched to Innostax’s managed team model with a dedicated tech lead. Despite the same product complexity, the entire output cadence changed completely.
You need a single person accountable for the team’s daily output and that person needs the authority and access to keep work moving.
The Most Common Mistake: Replacing People Before Fixing the System
The most expensive mistake a CTO makes when facing a slow engineering team is concluding too early that the problem is the people.
In most cases, developers who appear slow in a broken system perform significantly better once the system is fixed. Ticket size discipline, a trustworthy board, code review capacity, and clear ownership are strictly table stakes. When they are totally missing, even the strongest engineers will look terribly slow.
Before any performance conversation, run through this strict diagnostic fully. If you address all six steps and performance remains low, you finally have evidence-based grounds for a hard conversation. Until then, the data is heavily lying to you.
Common Mistakes to Avoid
- Measuring velocity in points, not outcomes: Story points are a proxy metric. A team closing 40 points but shipping broken features is not fast. Always measure the first-time-right rate alongside raw velocity points.
- Fixing the wrong layer: Teams blindly fix the symptom closest to the pain. The root cause is almost always upstream, like unclear requirements causing endless rework. Always fix exactly where the problem originates.
- Treating technical debt as optional: Skipping refactoring sprints is a terrible short-term trade. Two quick sprints of cleanup now are vastly cheaper than six months of deeply degraded velocity.
- Running standups without surfacing blockers: A standup where everyone says “no blockers” but the sprint still fails is entirely useless. The pure purpose of the standup is surfacing blockers.
- Assuming staging equals production: Unless you actively verify environment parity, assume they have heavily drifted. This single bad assumption creates massive classes of phantom bugs.
- Building a flat team with no lead: A capable team without a dedicated tech lead is always slower. Coordination overhead and ownership ambiguity will painfully compound across every sprint.
- Keeping QA out of requirements discussions: QA must never test against a developer’s loose interpretation of requirements. Always deeply involve QA in refinement so they know the exact original expectations.
A Note on Culture
None of this framework works in an environment where raising problems feels unsafe.
If developers fear looking incompetent, dangerous blockers go completely unresolved. If QA doesn’t quickly flag bad environment issues, bugs reach production. If the tech lead doesn’t safely push back on insane overcommitment, sprints fail predictably. If engineers wait for strict approval on tiny decisions, simple timezone gaps become awful multi-day delays.
Velocity is partly a structural process problem and partly a deep culture problem. The diagnostic perfectly addresses the rigid process. If you heavily fix the process and the team still hides early problems, your engineering culture is broken.
Summary: The 6-Step Diagnostic
| Step | What to Check | Key Signal | Fix |
| 1 | Project management board | Tickets over 3 days in dev; top-down estimates | Consumable tickets; developer self-estimation |
| 2 | Code review pipeline | Single reviewer; PRs bouncing; no automation | Scale reviewers; automate mechanical checks |
| 3 | First-time-right rate | Ticket bounces between dev and QA | Code quality refactor or requirements clarity |
| 4 | Production bug volume | Bugs consuming sprint capacity | Fix QA process, context, or staging/production parity |
| 5 | Ownership and coordination | Ambiguity, silent blockers, timezone delays | Explicit ownership; decision empowerment; context flow |
| 6 | Sprint planning | Commitments exceeding capacity | Capacity-based scoping; separate priority from scope |